

Pharma & Biotech
Discovery-to-clinic computational infrastructure — from target ID pipelines to trial-ready data systems.
TYPICAL CLIENT
A discovery or translational science team with a program advancing toward the clinic
Usually a VP of Computational Sciences, Head of Bioinformatics, or CTO at a biotech with at least one program past hit identification, who needs infrastructure that won’t need to be rebuilt at the next stage gate.
The problems that bring teams to us.
Infrastructure that doesn’t survive a stage gate
Discovery-stage tools built for a single push rarely hold up once a program advances toward IND-enabling studies, forcing a costly rebuild at the worst time.
Data scattered across discovery, translational and clinical silos
Each stage often uses different tools and formats, making it hard to trace a candidate’s full history from screening to trial.
Compliance bolted on too late
Security and regulatory alignment get treated as a pre-filing checklist item instead of an architecture decision, creating expensive rework.
Four places we plug into your program.
What each of these actually looks like day to day — not just the one-line version.
Discovery infrastructure
Early discovery is where the most computational ground gets covered in the shortest time, and where infrastructure decisions are cheapest to get right. We build target identification, virtual screening and generative design pipelines that plug into your existing compute and wet-lab workflows, so your team moves from a hit list to a validated lead without re-tooling every few months.
- Target identification pipelines built around your assay data and structural biology inputs
- Virtual screening at the scale of millions of compounds, tuned to your target class
- Generative design workflows for lead optimization, with medicinal chemistry constraints built in
Genomic & multi-omic data platforms
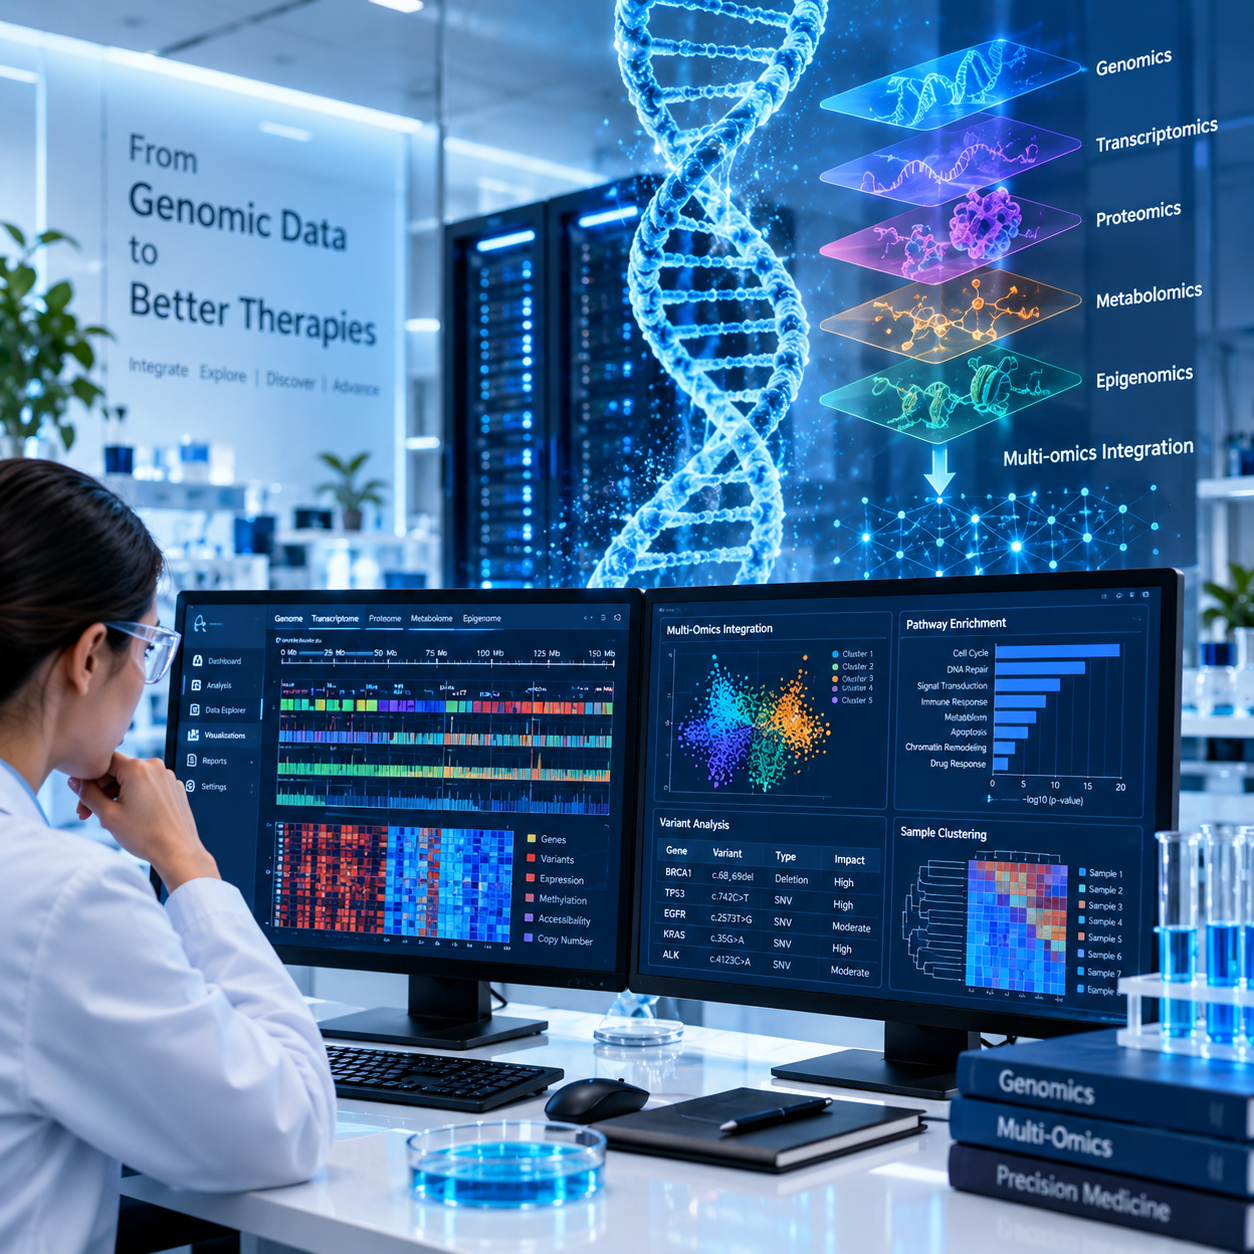
Discovery, translational and clinical teams typically work from different tools, formats and access rules, which makes it hard to trace a candidate’s full history or run analysis across stages. We build harmonized genomic and multi-omic data platforms that unify these datasets under one access model, so your bioinformatics core can query across the whole program instead of stitching together exports.
- Unified data model spanning genomic, transcriptomic, proteomic and phenotypic datasets
- Query layers built for bioinformatics teams, not just data engineers
- Version-controlled pipelines with full lineage back to raw sequencing data
Trial-ready data systems
As a program approaches IND-enabling studies, data systems need to hold up under regulatory scrutiny — audit trails, validation records and reporting a reviewer can trust. We build clinical data pipelines and reporting layers designed for that scrutiny from the start, so the move into trial-ready operations doesn’t mean rebuilding what already works.
- Audit-ready data pipelines with full traceability from raw data to reported result
- Reporting systems built to CDISC and regulatory submission standards
- Validation documentation prepared alongside the system, not after it
Compliance & security
Security and regulatory alignment are architecture decisions, not a pre-filing checklist. We design HIPAA, GDPR and GxP-aligned systems for anything touching patient or proprietary data — access controls, encryption and audit logging built into the platform from day one, not layered on after a partner asks for it.
- Role-based access control and encryption by default across every environment
- GxP-aligned validation and change control for regulated systems
- Independent security audits before diligence or filing, not during it
One partner across the entire discovery-to-clinic timeline.
Most computational partners specialize in one stage — discovery, or clinical data, but rarely both. We work across the full timeline, which means the data infrastructure you build in discovery is still usable when a candidate reaches clinical trials.
That continuity saves months of re-platforming every time a program crosses a stage gate.
How we approach this field
Four stages, shaped around how this industry actually operates.
Understand your pipeline stage
We map where your program sits — discovery, preclinical or clinical — and what infrastructure already exists.
Design for the next stage, not just this one
Systems are architected to extend cleanly as a program advances, instead of requiring a rebuild.
Ship in validated increments
Pipelines and platforms are delivered and validated against real program data at each milestone.
Support through the next stage gate
We stay engaged as your program advances, extending the same infrastructure rather than handing off to a new vendor.
Nuclyra is the only partner we didn’t have to re-explain our program to when we moved from discovery into IND-enabling studies.
Before you reach out
Yes, in fact most of our pharma and biotech engagements start pre-IND, when infrastructure decisions are cheapest to get right.
Absolutely, most engagements start scoped to a single stage; we just build in the extensibility for the next stage.
Yes, this is standard for every pharma and biotech engagement we take on.
Where is your program in the pipeline?
Tell us your stage and current infrastructure — we’ll map what’s needed for the next one.