

Genomic Data Intelligence Platform
A unified analytics layer for large-scale genomic datasets, enabling researchers to explore variants, phenotypes, sequencing metrics, and biological insights without writing SQL.
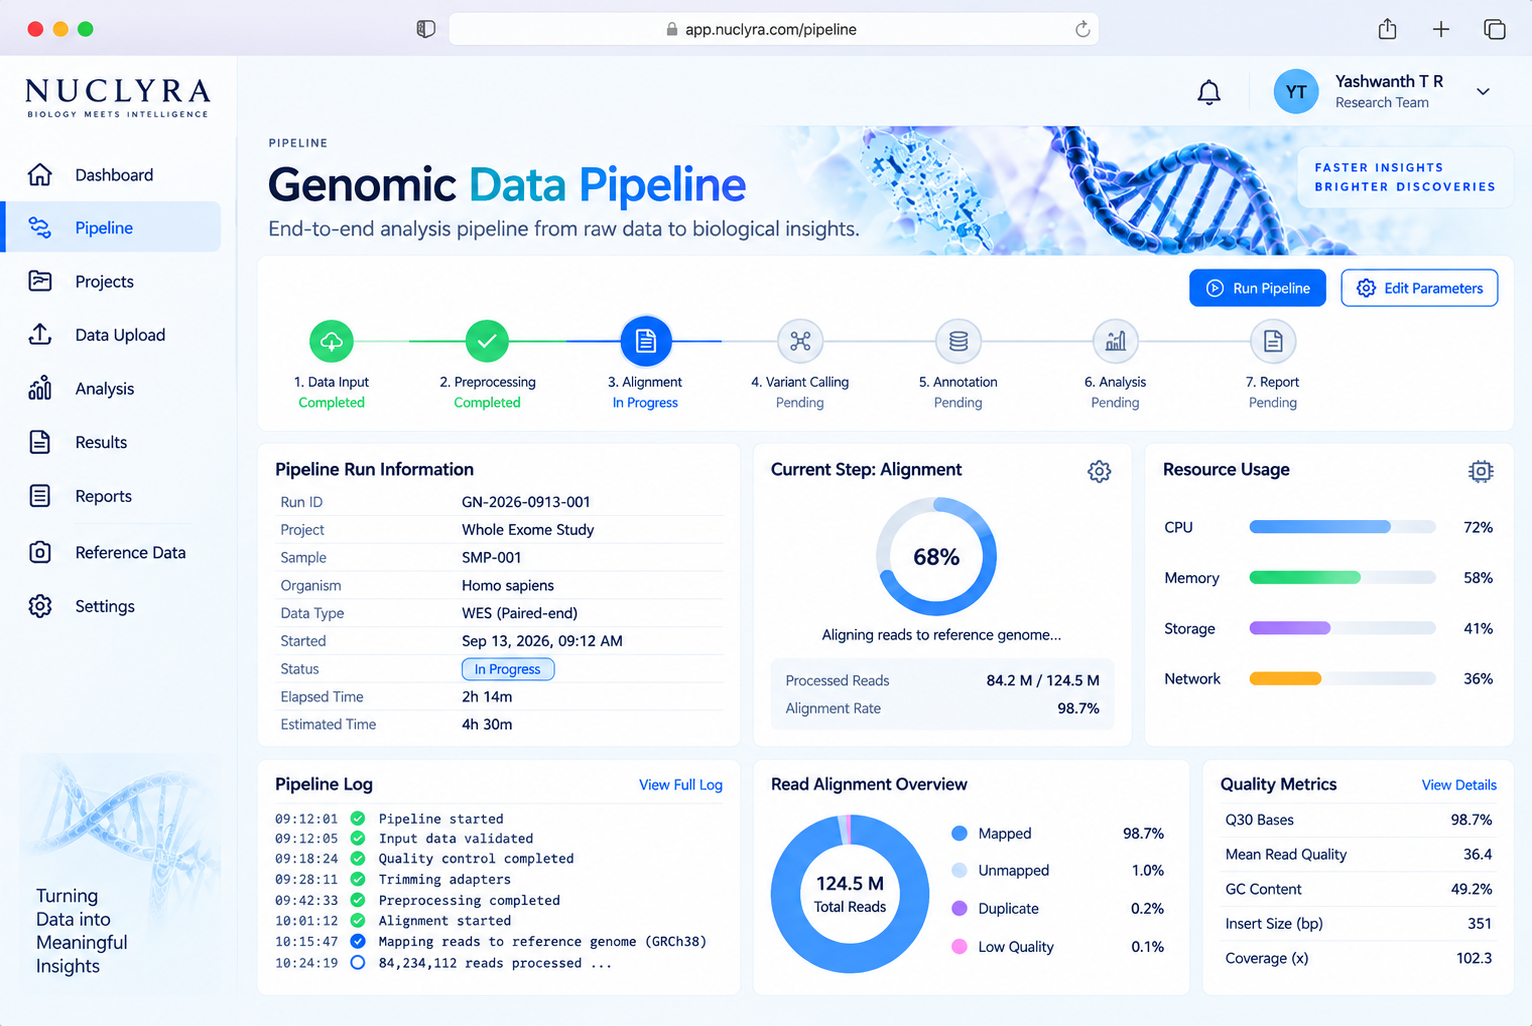
What’s inside
No-code query builder
Filter and cross-reference variants, phenotypes and cohorts through a visual interface — no SQL required.
Harmonized data layer
Sits on top of your harmonized genomic warehouse, so every query reflects the same underlying source of truth.
Cohort-scale performance
Built to stay responsive across millions of variants and tens of thousands of samples.
Access control built in
Row- and column-level permissions respect each contributing institution’s data-sharing terms.
What this looks like day to day
Three concrete scenarios Genomic Data Intelligence Platform is built to handle.
A researcher builds their own cohort
A scientist filters tens of thousands of samples by variant, phenotype and ancestry through the visual query builder, and has a defined cohort in minutes — instead of filing a data request and waiting a week for the core team to run it.
Following up on a signal the same day
A new association turns up in one study; the team cross-references allele frequency and phenotype prevalence across every connected cohort before end of day, rather than end of month.
A compliance officer reviews access, not requests
Instead of approving data pulls one at a time, the compliance team reviews a standing, timestamped log of who queried which cohort and when — ready to hand to an auditor as-is.
A visual query is still a governed query.
Every filter a researcher drags into the query builder compiles down to a query against your harmonized warehouse — the same one your pipelines already write to. Nothing gets copied out into a side database, so there is only ever one source of truth to keep in sync.
Before that query runs, it passes through a permissions layer that checks the requesting user against row- and column-level rules set per cohort and per institution. A researcher only ever sees the slice of data their data-sharing agreement allows — the query builder simply won’t render fields they aren’t entitled to, so there’s nothing to accidentally expose.
The result: the same visual interface works whether one lab is exploring its own dataset or forty institutions are querying a shared federated warehouse under different terms.
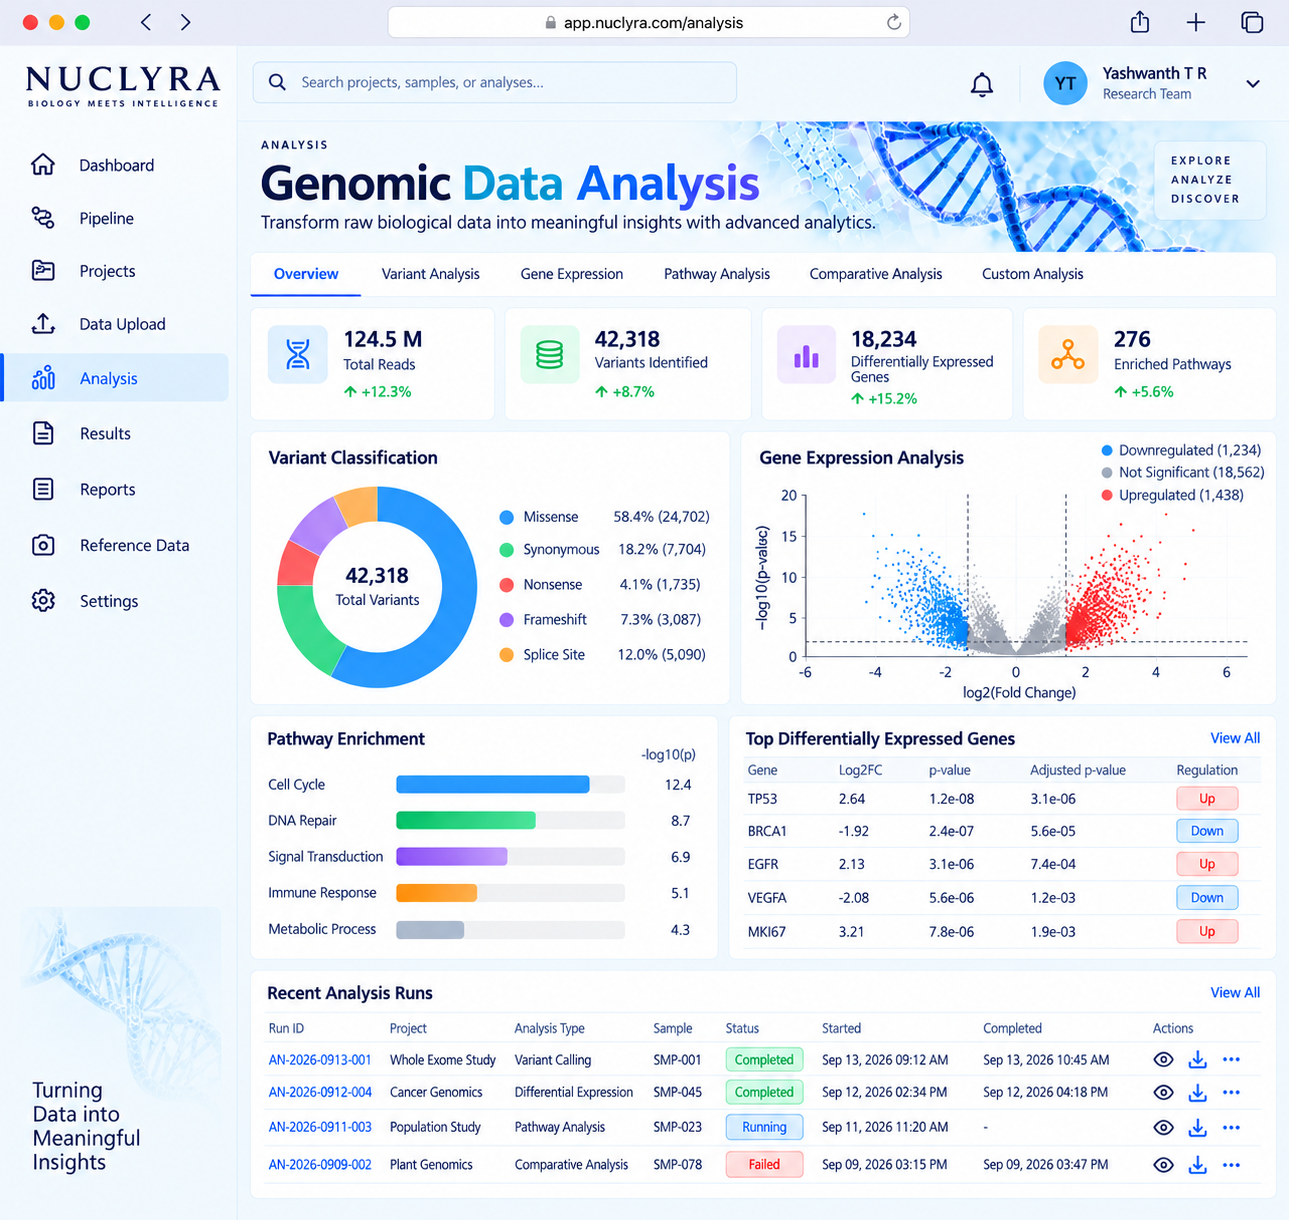
From connecting your data to sharing a result
Connect your warehouse
Genomic Data Intelligence Platform connects to your existing harmonized genomic data warehouse — no data migration required.
Configure access
Row- and column-level permissions are configured to match your existing data-sharing agreements.
Query visually
Researchers filter and cross-reference variants and phenotypes through a no-code interface.
Export & share
Results export directly to downstream analysis tools or shareable reports.
Before and after Genomic Data Intelligence Platform.
Manual data requests
- Each cross-cohort question requires a new data pull
- Turnaround measured in days or weeks
- No standard way to track who accessed what
With Genomic Data Intelligence Platform
- Researchers query directly, no request needed
- Turnaround measured in seconds
- Every access logged automatically
Plugs into what you already use
Genomic Data Intelligence Platform turned a two-week data request into a five-minute self-serve query.
Before you reach out
No, Genomic Data Intelligence Platform connects to your existing harmonized warehouse; there’s no data migration required.
Yes, row- and column-level permissions can be configured per user, per cohort, or per institution.
Genomic Data Intelligence Platform is built for cohort-scale performance; deployments regularly handle millions of variants across tens of thousands of samples.
Want to see Genomic Data Intelligence Platform on your own data?
Book a walkthrough — we’ll tailor the demo to your warehouse and use case.