

Bioinformatics Pipeline Platform
Orchestrate and monitor bioinformatics pipelines — schedule, version, track, and audit every run of your Nextflow or Snakemake workflows.
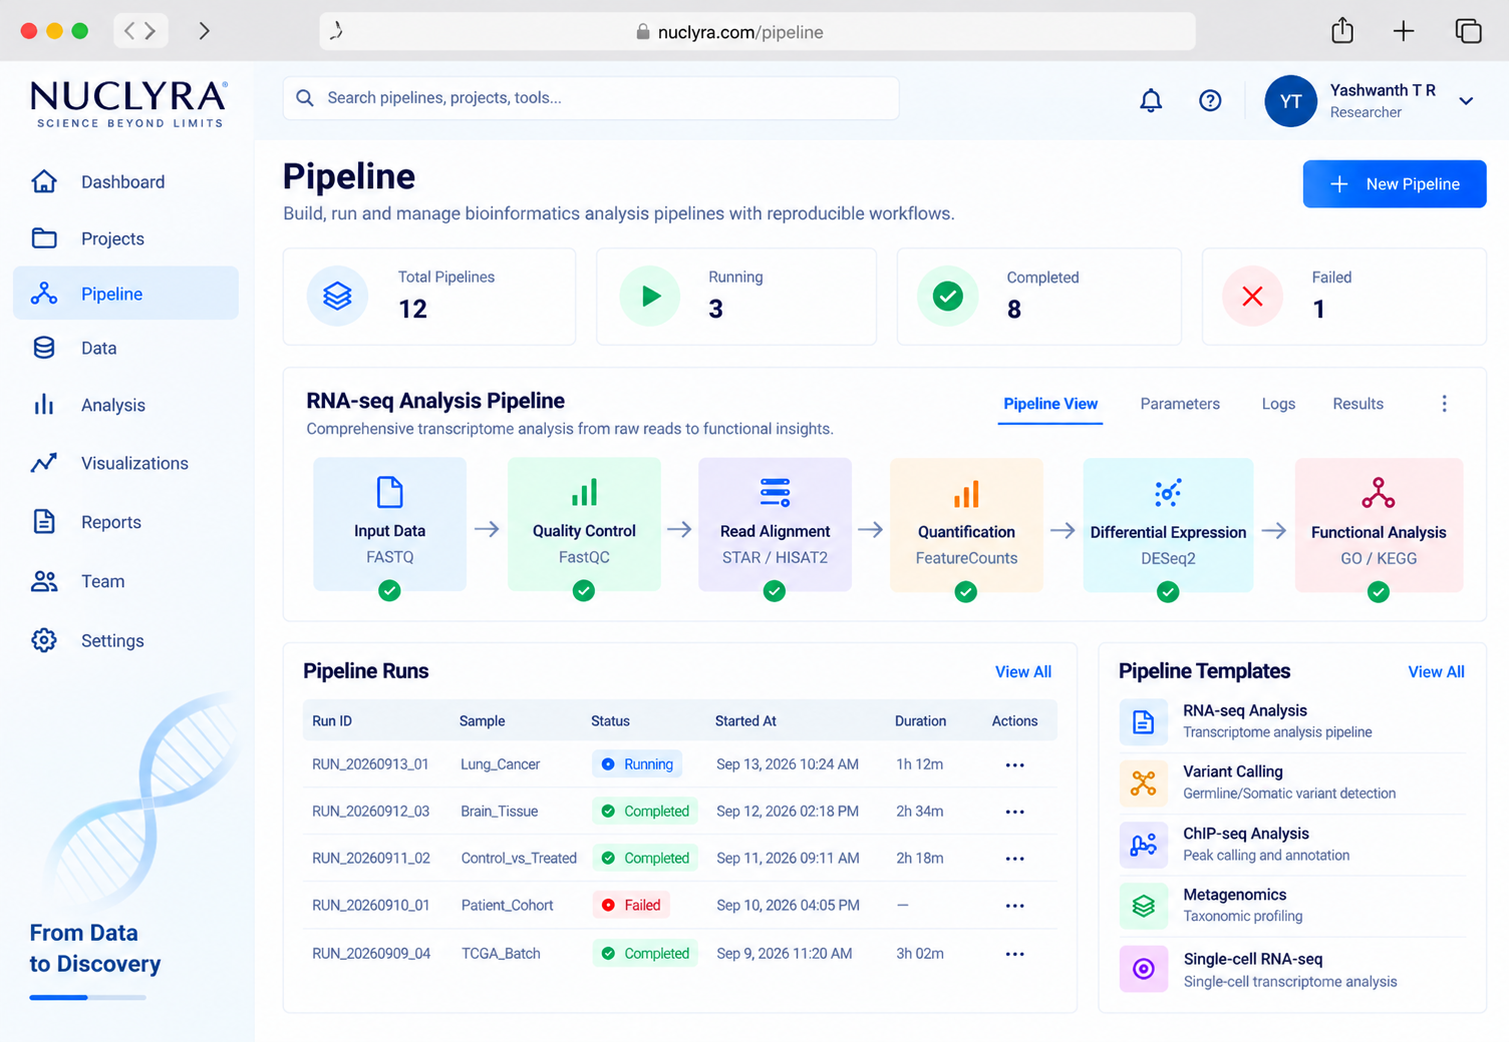
What’s inside
Pipeline orchestration
Schedule, queue and manage Nextflow and Snakemake pipeline runs across HPC and cloud compute.
Full run auditing
Every run is versioned and logged, with full provenance from raw input to final output.
Failure alerting
Automated QC gates and failure alerts catch problems before they reach a researcher’s desk.
Cost-aware scaling
Compute scaling recommendations keep cloud costs predictable as pipeline volume grows.
What running pipelines on Bioinformatics Pipeline Platform looks like
Three concrete scenarios Bioinformatics Pipeline Platform is built to handle.
Nightly variant-calling across a shared cluster
Dozens of samples queue automatically across whatever HPC or cloud compute is free that night, instead of researchers manually coordinating who runs what and when.
Catching a bad reference path before it burns a week
An automated QC gate flags a pipeline pointed at the wrong reference build within minutes of the run starting, instead of a researcher discovering it after several days of compute.
Producing a full audit trail for submission
Every input file, parameter and pipeline version behind a result is already logged, so answering ‘how was this generated’ for a regulatory submission takes minutes, not a week of digging through logs.
Your pipelines, wrapped in a layer that watches.
Bioinformatics Pipeline Platform doesn’t replace your Nextflow or Snakemake workflows — it wraps them. Each registered pipeline keeps its own DAG of tasks; Bioinformatics Pipeline Platform adds a scheduling, monitoring and provenance layer around it, so nothing has to be rewritten to get the benefit.
As a run executes, every task’s inputs, parameters, container image and output are recorded against that run’s version. QC gates you define run at task boundaries, so a bad input or a failing step raises an alert immediately instead of quietly propagating downstream.
Because that provenance record is captured automatically, tracing any output back to the exact code, container and inputs that produced it is a lookup, not an investigation.
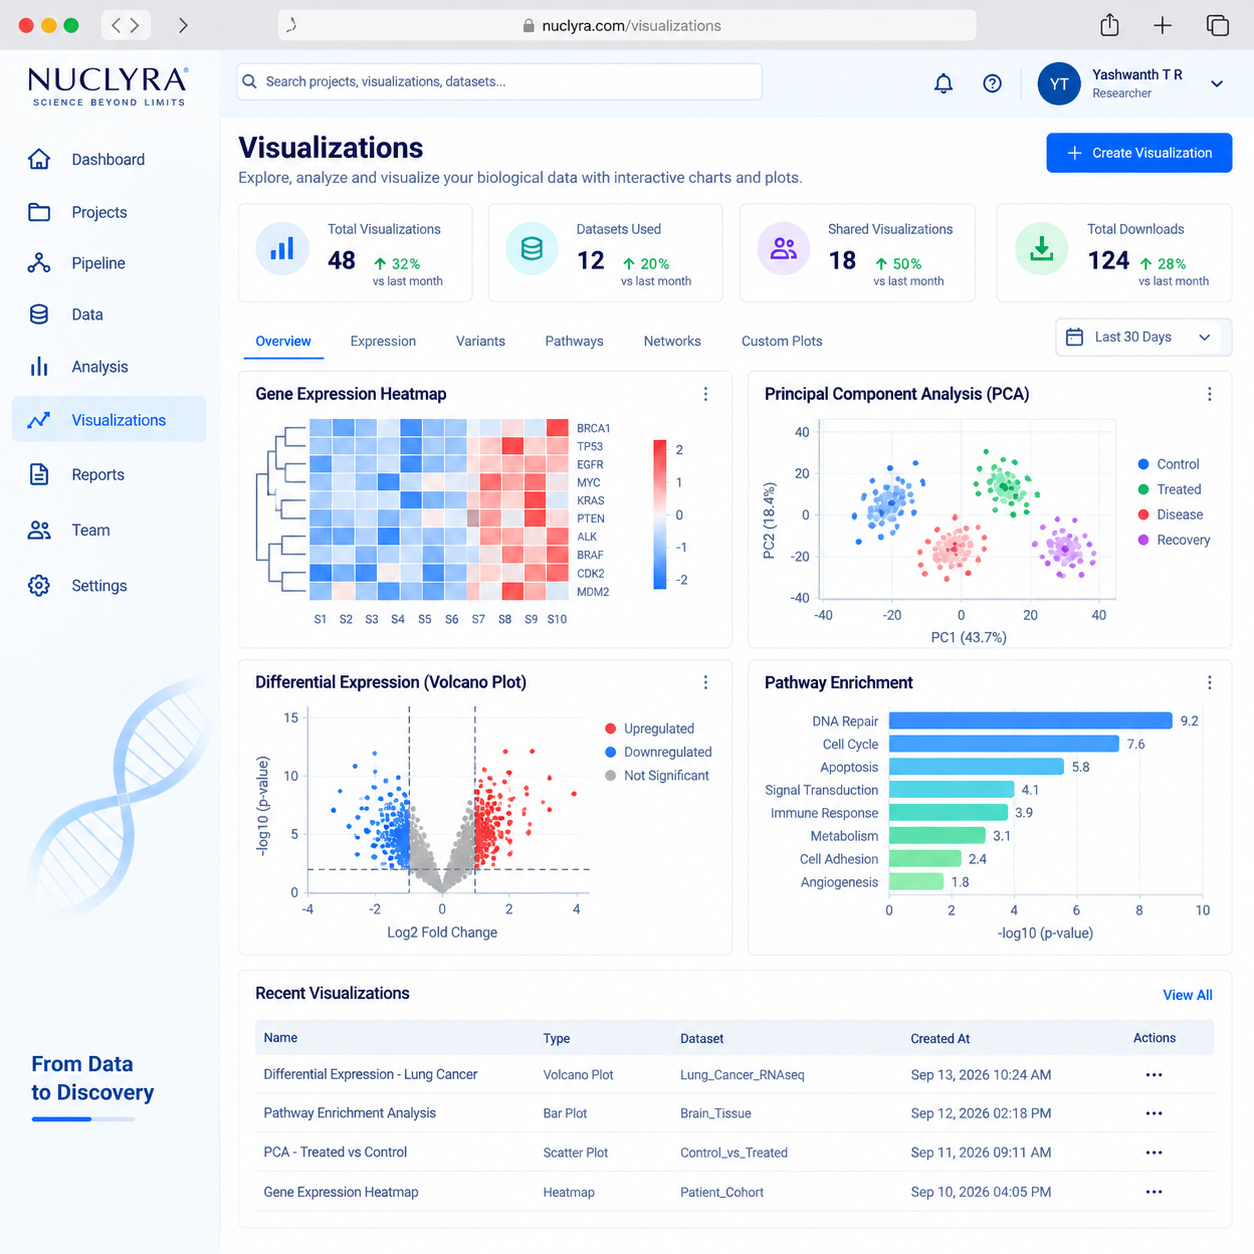
From connecting your data to sharing a result
Register your pipelines
Existing Nextflow or Snakemake pipelines are registered with Bioinformatics Pipeline Platform with no rewrite required.
Schedule & queue runs
Runs are scheduled and queued across your available HPC or cloud compute.
Monitor in real time
Dashboards and alerts surface run status, failures and QC flags as they happen.
Audit any result
Every output can be traced back to the exact pipeline version and inputs that produced it.
Before and after Bioinformatics Pipeline Platform.
Patchwork of scripts
- Cron jobs and manual log checks
- No single source of truth for run history
- ‘Which version made this result’ is a mystery
With Bioinformatics Pipeline Platform
- One dashboard for every pipeline run
- Full versioned run history, always queryable
- Every result traceable to its exact inputs
Plugs into what you already use
We finally have one place to look when someone asks ‘what changed since last month’s run.’
Before you reach out
No, existing Nextflow or Snakemake pipelines are registered as-is; no rewrite is required.
Yes, it orchestrates runs across HPC clusters, cloud compute, or a mix of both.
It provides scaling recommendations and cost visibility per pipeline, so runaway compute costs get caught early.
Explore related work
Bioinformatics Pipeline
The pipeline design service Bioinformatics Pipeline Platform is built to orchestrate.
View PRODUCTGenomic Data Intelligence Platform
Where Bioinformatics Pipeline Platform output goes to become queryable data.
View PHARMAPharma & Biotech
How pharma discovery teams use Bioinformatics Pipeline Platform in production.
ViewManaging pipelines through a patchwork of scripts?
Book a walkthrough — we’ll show you Bioinformatics Pipeline Platform running against a pipeline like yours.